Press Space to continue
Press Space to continue
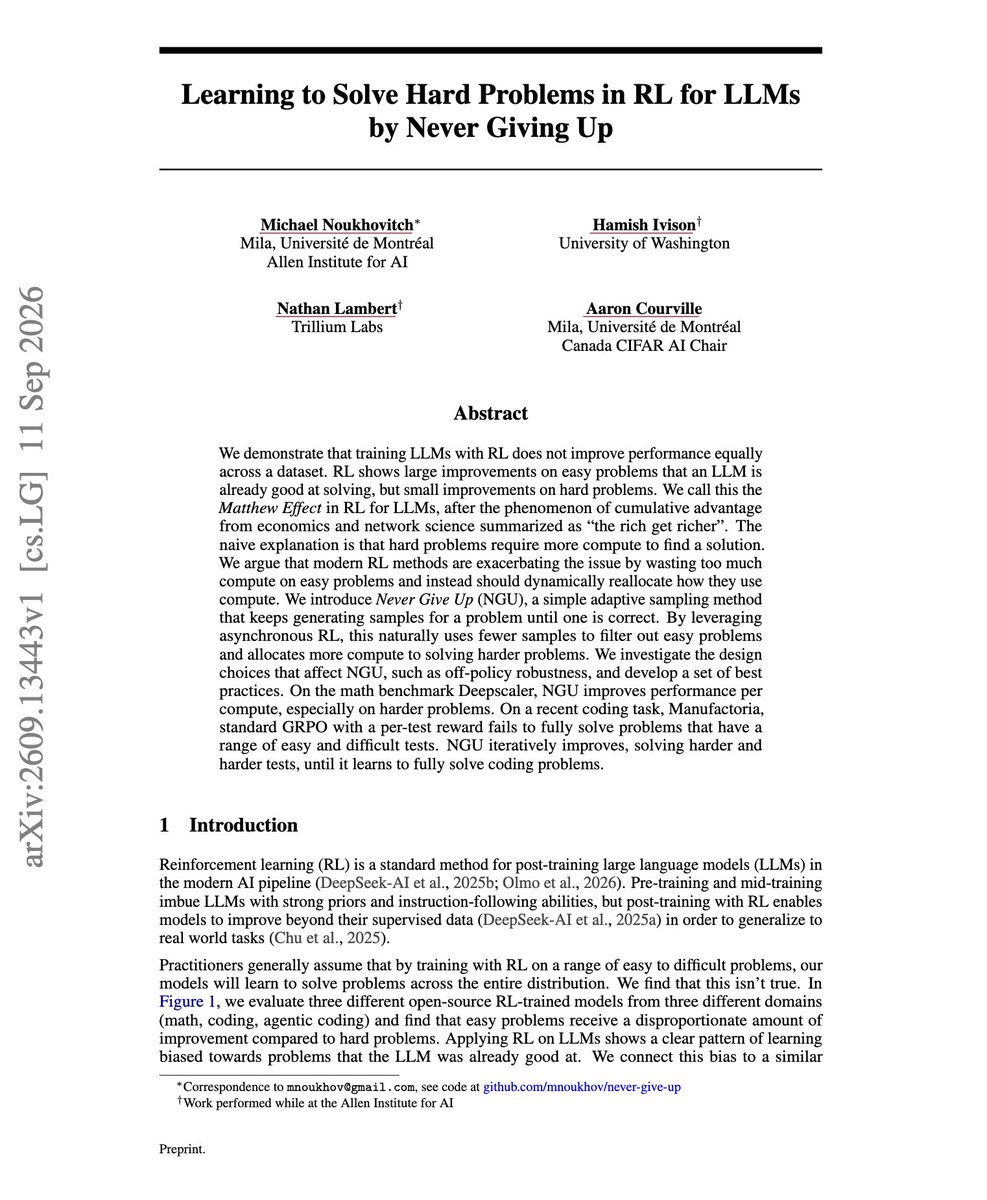
“Learning to Solve Hard Problems in RL for LLMs by Never Giving Up” This paper shows RL has a Matthew Effect, disproportionately improving problems the model can already solve while barely improving the hardest ones. So they fix this by dynamically reallocating sampling compute, quickly filtering easy prompts while repeatedly sampling hard prompts until a correct solution is found. This lets RL progressively learn from harder problems instead of wasting compute on already-solved…