Press Space to continue
Press Space to continue
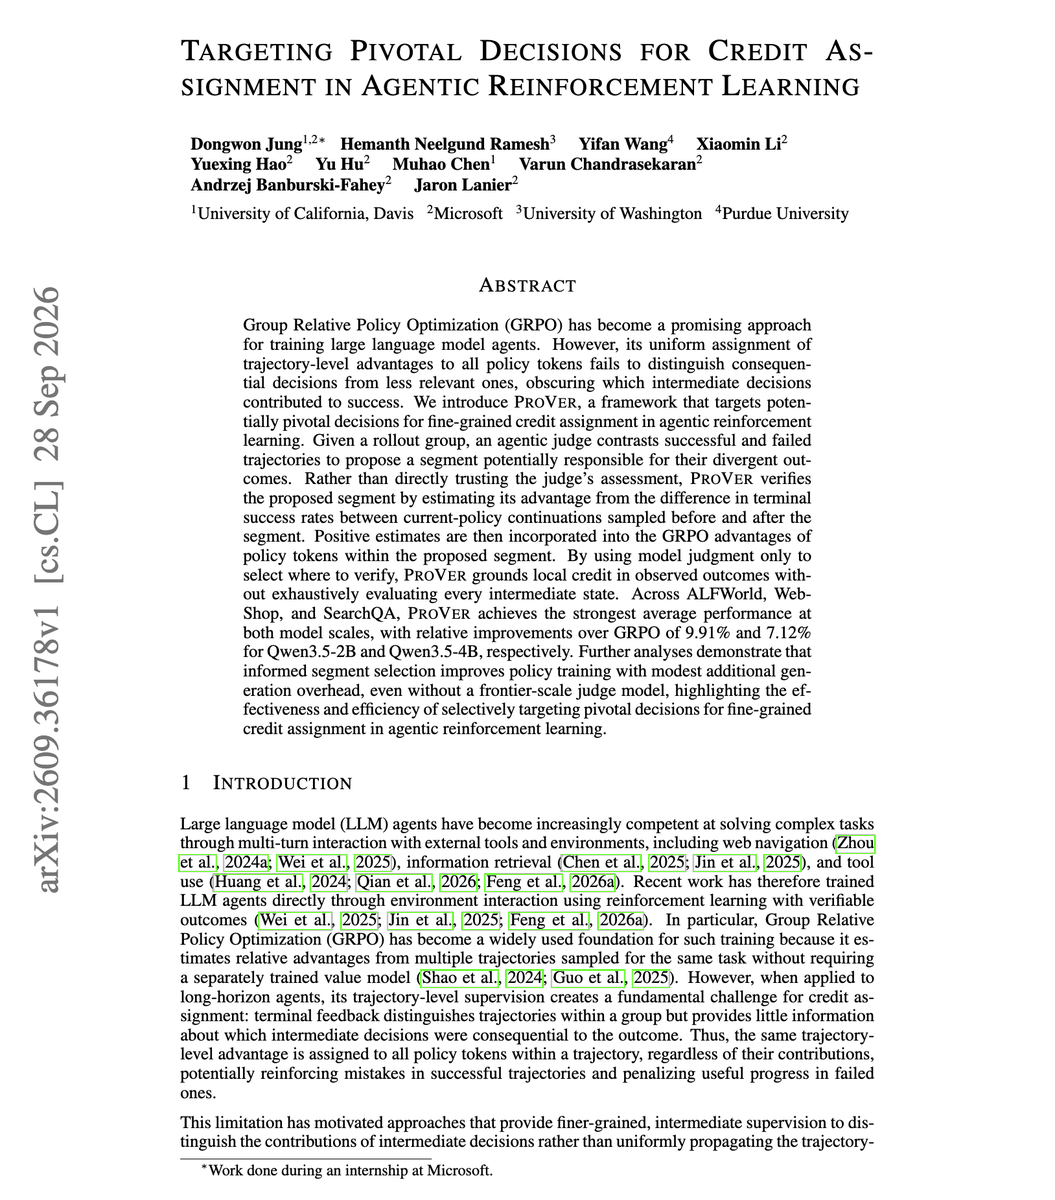
Good paper on credit assignment for agent RL. The main finding is that you want an LLM judge to choose where to check a trajectory, and the rollouts to decide how much credit that step gets. GRPO gives every token in a trajectory the same advantage, so the training signal cannot tell the decisive step from the rest. ProVer has a judge compare successful and failed rollouts and name the segment it thinks caused the difference. It then samples continuations from just before and just after that…