Press Space to continue
Press Space to continue
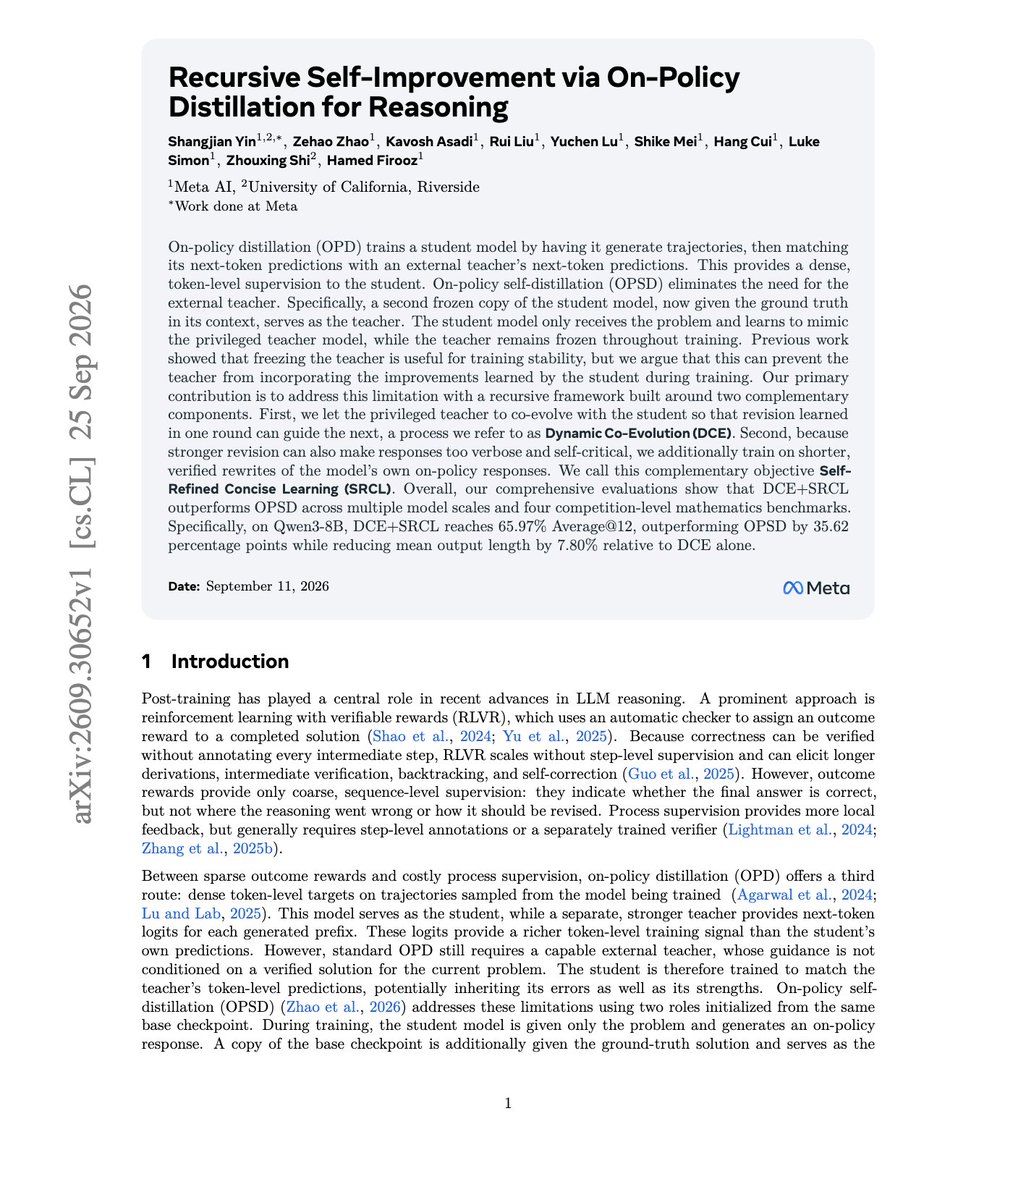
"Recursive Self-Improvement via On-Policy Distillation for Reasoning" What if you make on-policy distillation recursive? This paper proposes that after each round, the improved model becomes both the next student and the new gold-conditioned teacher, letting better reasoning feed into future supervision. They also train on shorter verified self-rewrites to stop stronger reflection from simply producing longer reasoning. On Qwen3-8B, Average@12 jumped from 30.35% with frozen-teacher OPSD to…