Press Space to continue
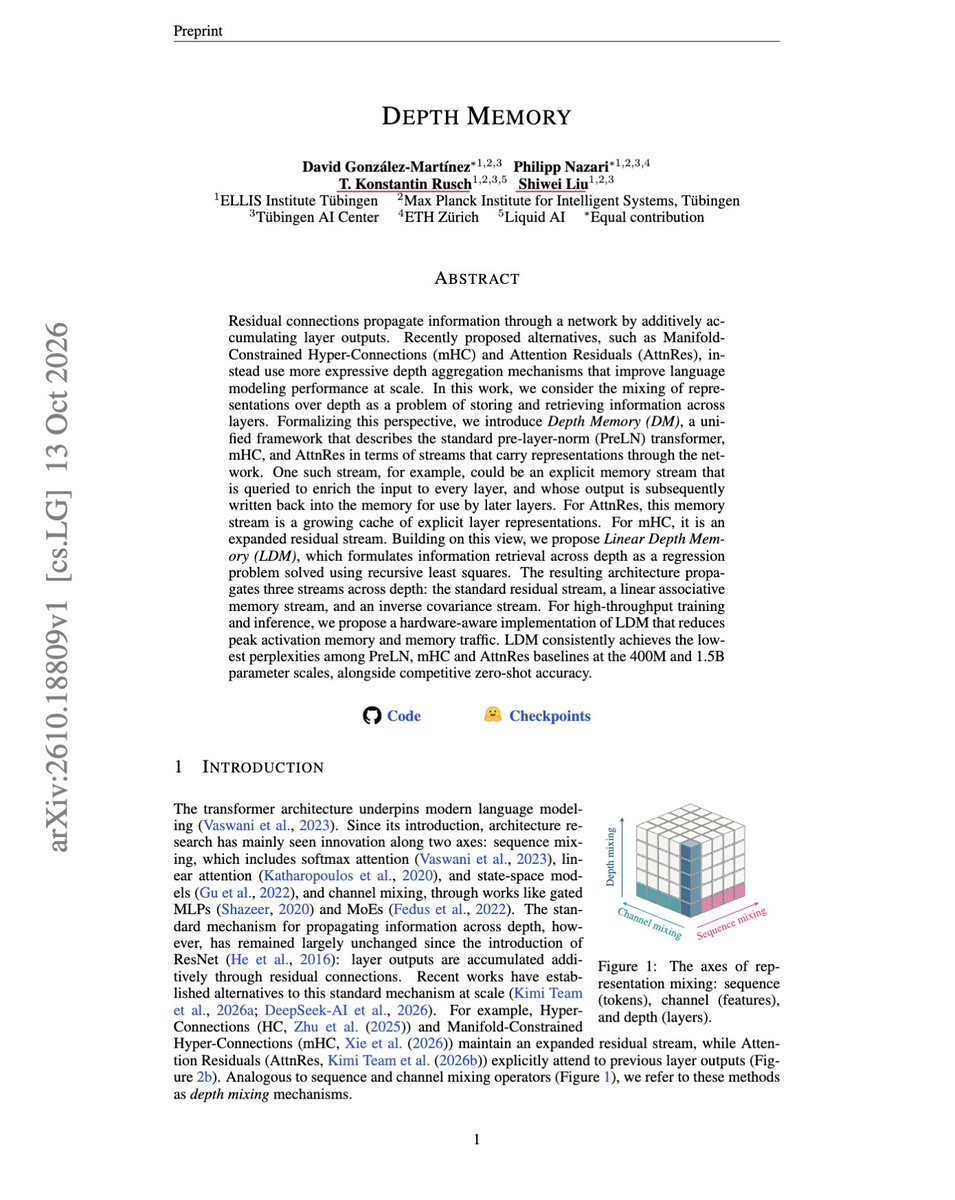
Depth Memory" Attention Residuals stores earlier Transformer
Press Space to continue
"Depth Memory" Attention Residuals stores earlier Transformer layer outputs for retrieval but this memory grows with depth. Linear Depth Memory (LDM) maintains a fixed-size memory across layers, using recursive least squares to store and retrieve earlier layer information alongside the standard residual stream. On 400M and 1.5B models, LDM achieves lower perplexity than standard residuals, mHC, and AttnRes, while maintaining competitive zero-shot accuracy and comparable throughput with…