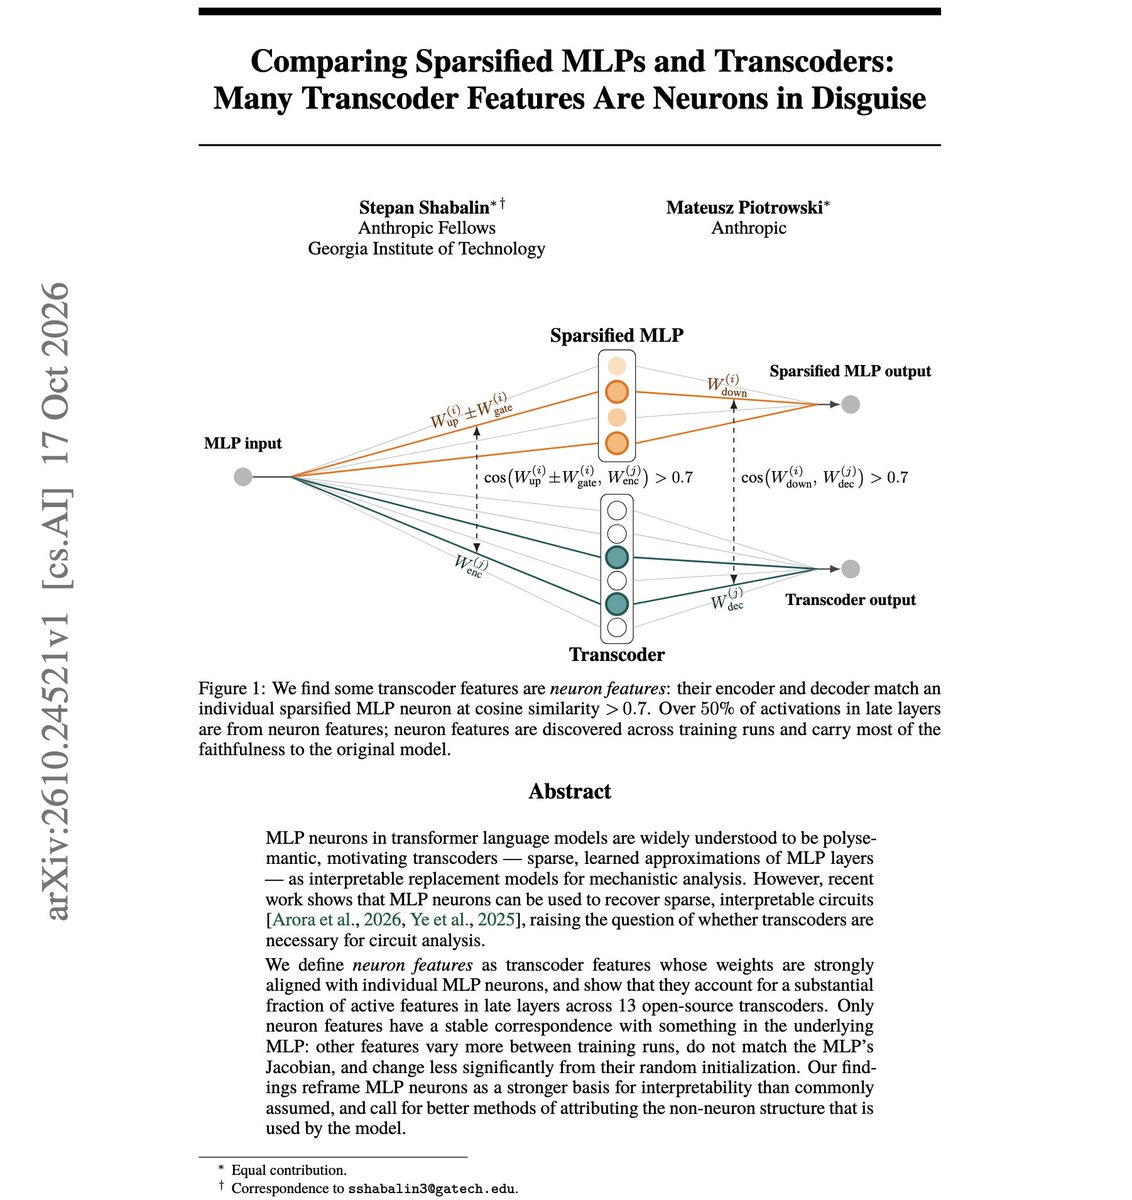
Press Space to continue
Interesting work from Anthropic
Press Space to continue
Interesting work from Anthropic. They reframe MLP neurons as a stronger basis for interpretability than commonly assumed. It is standard practice to study circuits with transcoders, because individual MLP neurons are considered too polysemantic to interpret. They find that many active transcoder features in late layers are close copies of single MLP neurons. They measure this across 13 open-source transcoders. These neuron-aligned features are also the only ones with a stable link to the…