Press Space to continue
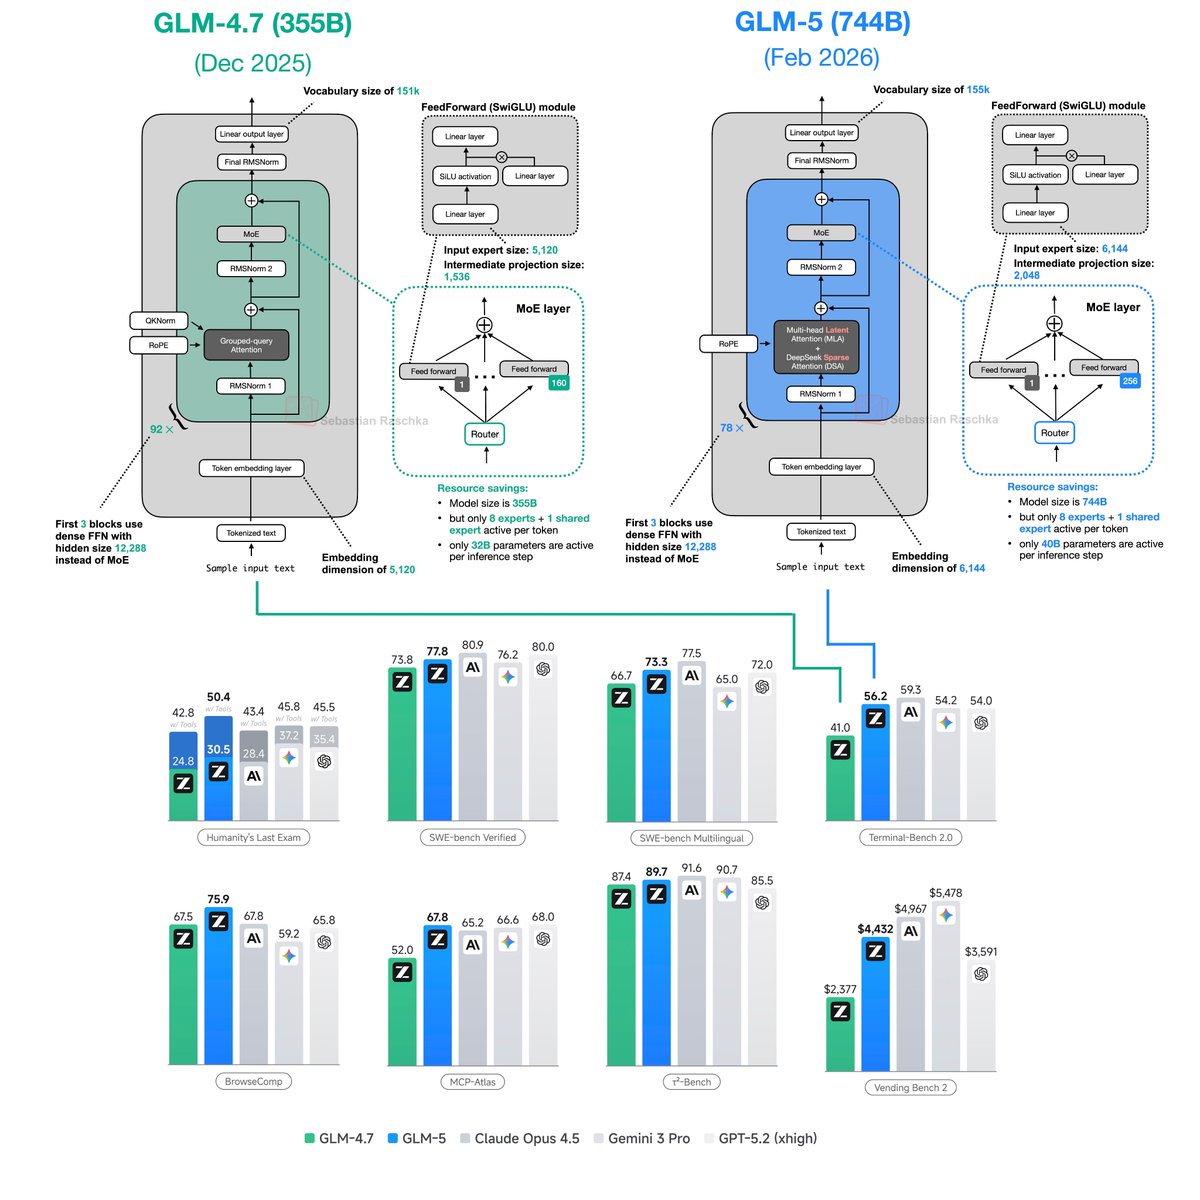
GLM-5 Architecture Uses Multi-Head Latent Attention
Press Space to continue
Curated tech Twitter/X posts on AI, startups, and product development—signal without the doomscroll, updated on weekdays.
Press Space to continue
Press Space to continue