Press Space to continue
Press Space to continue
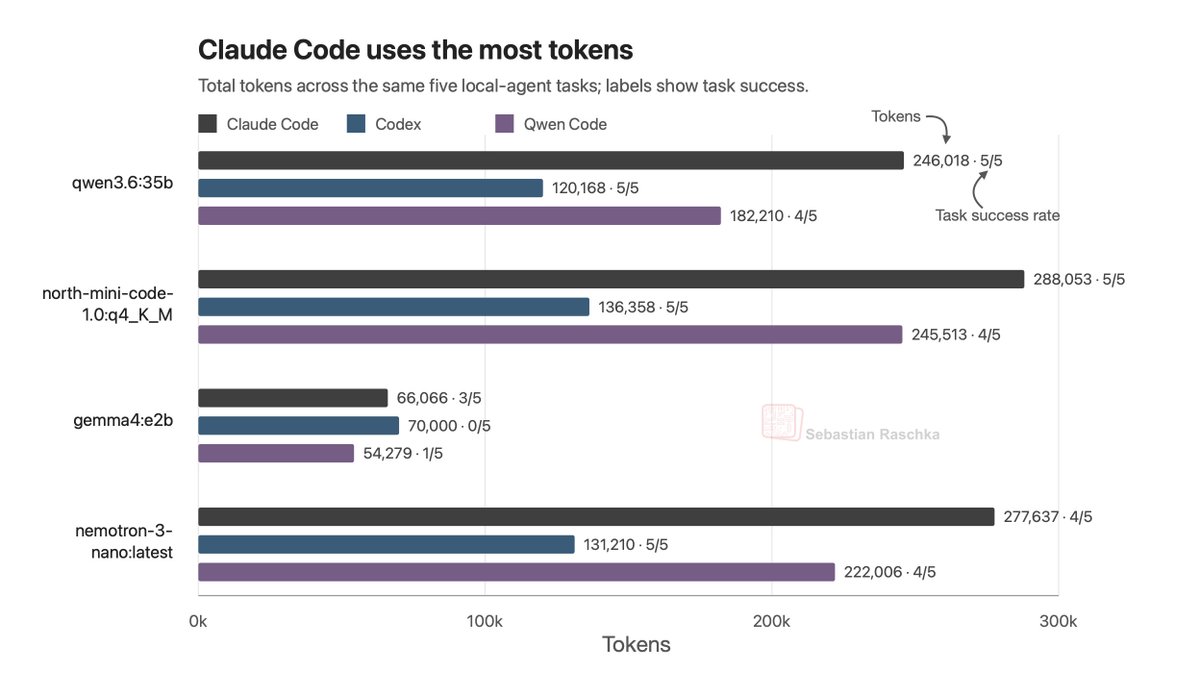
Have been taking different local open-weight LLMs for a test drive in different harnesses (Qwen-Code, Codex, Claude Code). 30B Mixture-of-Expert models are kind of a nice sweet spot and can solve challenging problems. And they get roughly 40 tok/sec on a Mac or DGX Spark, which is similar to GPT 5.5 in a Pro subscription and totally useable for everyday work. More interesting is also the harness choice! Claude Code seems to be using 2x many tokens as Codex. Gemma 4 E2B is here just for…