Press Space to continue
Press Space to continue
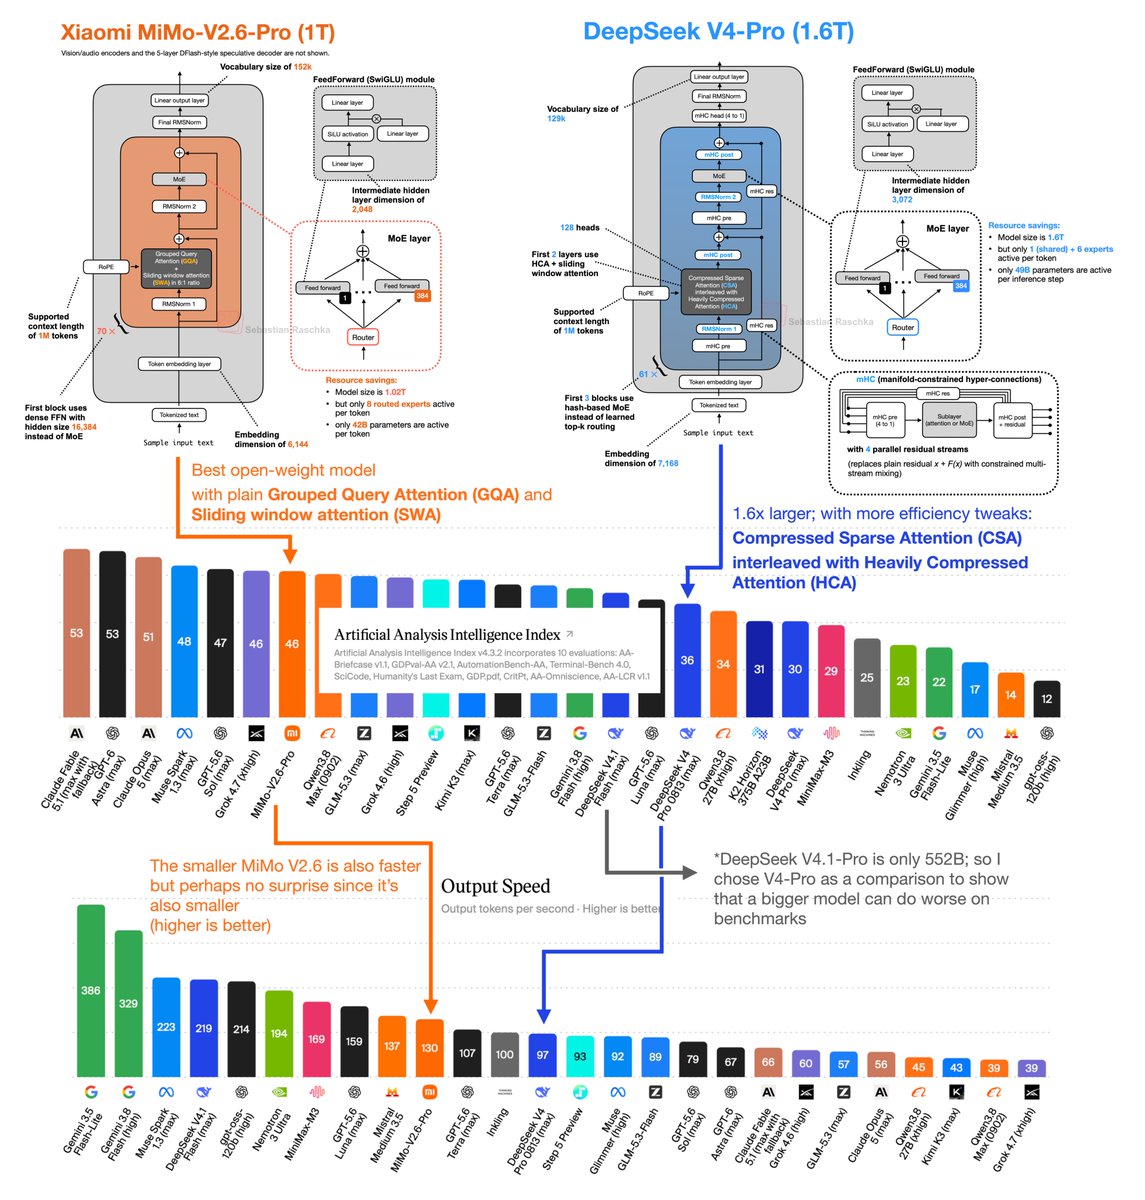
MiMo-V2.6 is "simply" the best (for now). Despite its simple architecture design it's currently No.1 in the open-weight benchmarks (weighted average). With "simple," I mean a classic Grouped Query Attention (GQA) with Sliding Window Attention (SWA) at a tiny 128-token window size. So, that underlines one of the points I've been trying to make in recent months: most of the progress still comes from the data and post-training recipe improvements. Fancy attention variants are just mostly…
ArtificialAnlys@ArtificialAnlys19h ago
MiMo-V2.6-Pro debuts as the top open weights model on the Artificial Analysis Intelligence Index (46). At $0.13 per Intelligence Index task, it lands on the Intelligence vs. Cost per Task Pareto frontier @Xiaomi has just released MiMo-V2.6-Pro, an open weights model with major advances in intelligence over its predecessor, MiMo-V2.5-Pro (Intelligence Index: 26). Despite the improvement, it retains the same attractive pricing at $0.435 per 1M input tokens (with a 99% cache-hit discount) and $0.87 per 1M output tokens. This makes MiMo-V2.6-Pro one of the most cost-efficient models to deploy. MiMo-V2.6-Pro is an MoE model with 1.02T total parameters and 42B active parameters. Stay tuned for additional analysis of the model. Check out MiMo-V2.6-Pro full benchmarking breakdown here: https://t.co/czBJhQKuWJ