Press Space to continue
Koi doubles usable GPU cluster capacity for LLM serving
Press Space to continue
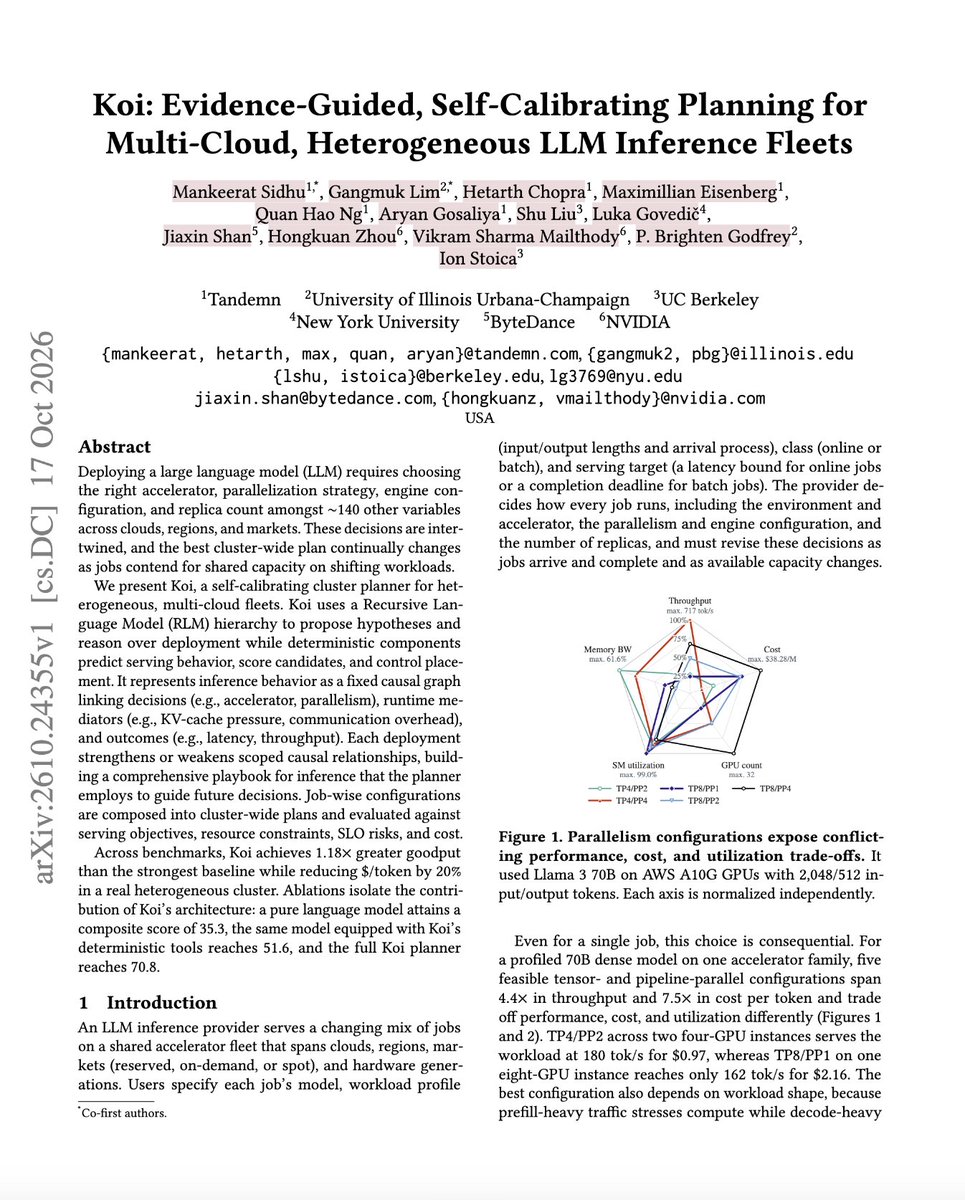
"Koi: Evidence-Guided, Self-Calibrating Planning for Heterogeneous LLM Inference Fleets" Deploying LLMs across heterogeneous GPU clusters requires jointly optimizing hardware selection, parallelism, serving configurations, and resource allocation across competing workloads. Existing approaches often optimize individual deployments or learn from end-to-end performance without identifying the underlying causes of performance differences Koi introduces a self-calibrating planning algorithm that…