Press Space to continue
Training LLMs as agent organizations with RLCR
Press Space to continue
Really digging this new arc of specialized RL models. Bullish on this effort to understand and unlock collective intelligence. Highly recommend checking out the technical report. RLCR is just one of the latest efforts to train LLMs as agent organizations. Why is this a big deal, and why is it necessary? Coordination and organization are important primitives as we move into agentic long-horizon work. Agents should natively support these capabilities, which is mostly done through harnesses…
GenReasoning@GenReasoning1d ago
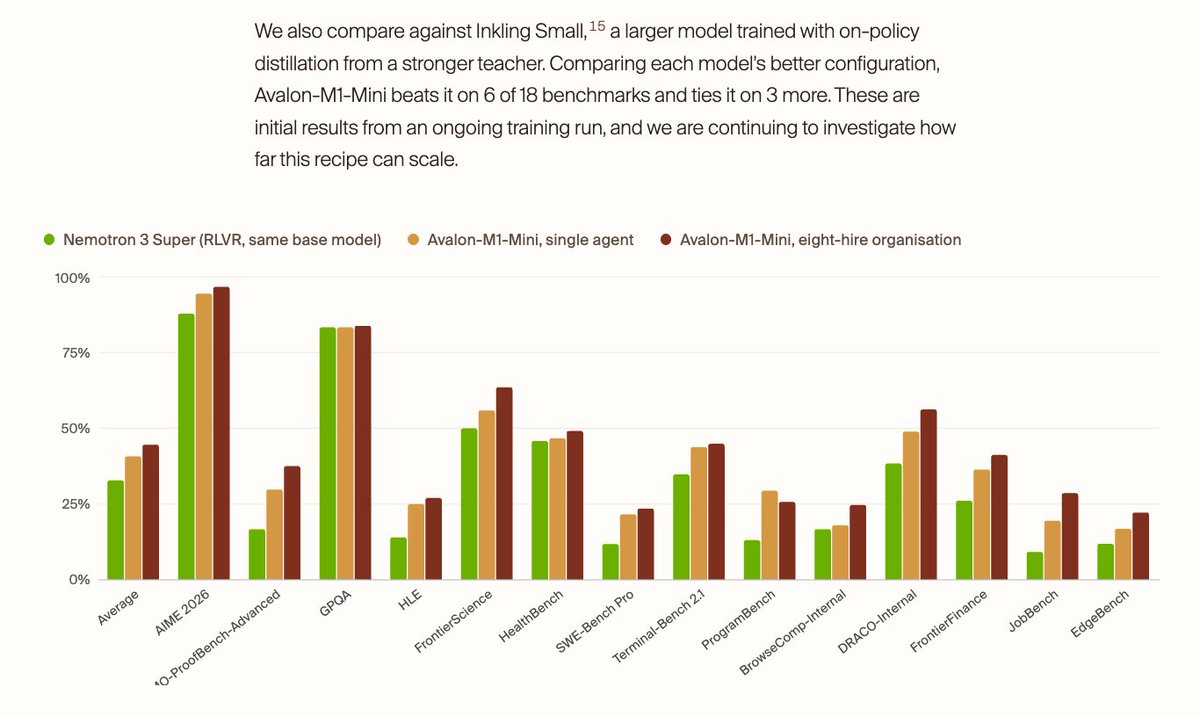
Introducing Reinforcement Learning from Collective Rewards (RLCR). RLCR is a recipe that trains language models as agent organisations, which share a message board and workspace. We use it to train Avalon-M1-Mini (120B) and study its behaviour. We find a number of interesting results, including: 🛠️ Learnt organisational hierarchies and divisions of labour 🕵️ Increased collective verification, through hires of verifiers and testers 👥 The rise of collective thinking, where agents think more about other agents and how to help them We believe RLCR can provide a laboratory for studying collective intelligence and multi-agent safety. Blog post and technical report 👇