Press Space to continue
Press Space to continue
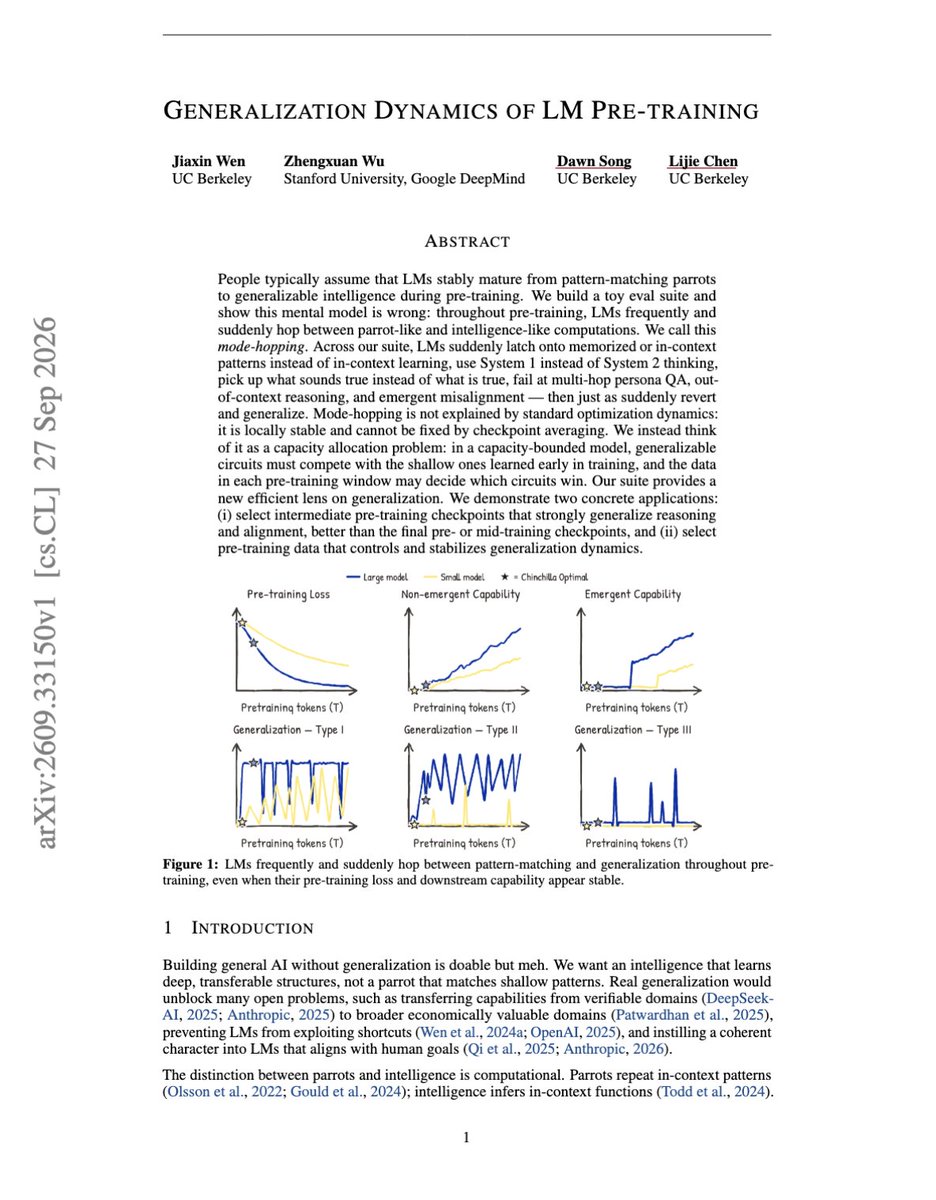
More pre-training doesn't necessarily mean better generalization? This new paper discovers mode-hopping, where LLMs repeatedly switch between shallow pattern-matching and actual generalization, even while training loss remains stable. For example, OLMo3-32B went from 81% accuracy to 0%, then back to 81.7% within just 40B training tokens. On top of that, selecting an earlier 4.5T-token checkpoint instead of a 4.9T one improved GPQA transfer after math fine-tuning (36.3% vs 29.8%) and…