Press Space to continue
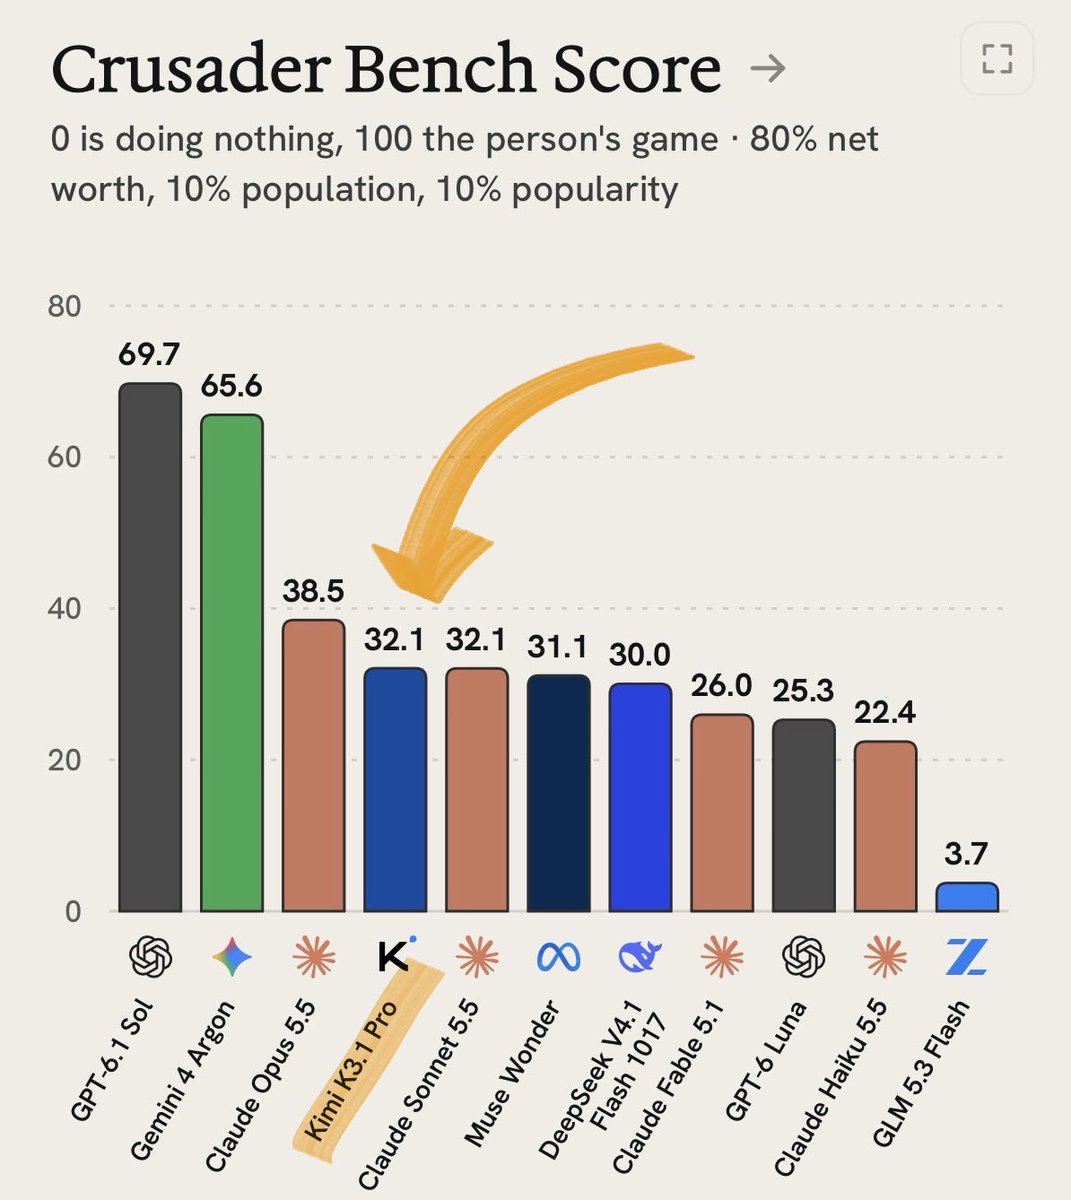
Kimi K3.1 Pro Scores Just Below Opus 5.5 on CrusaderBench
Press Space to continue
Just finished running Kimi K3.1 Pro on CrusaderBench. it scored pretty descent, just below Opus 5.5, and on the same score as Sonnet 5.5. some details: > all models run at “medium” reasoning. Kimi is set to “high” since it doesn’t have a “medium”. but for reference, on the same map, Kimi used ~550 tokens a turn, Gemini 4 Argon ~1,340, Opus 5.5 ~290 and GPT-6.1 Sol ~100. > Kimi’s reasoning is weirdly compact. "Pop48, idle24 cap -> growth stopped. I'll build jobs now." "payback18min, not…